Advanced Data
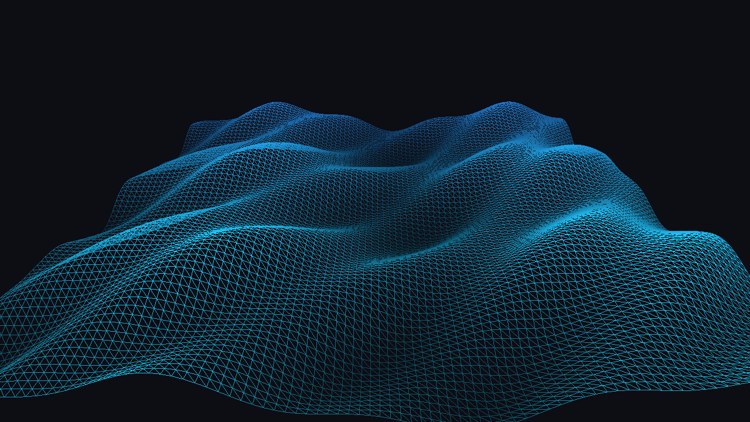
We have been putting vertex data, indices and constants into buffers since Hello Triangle, nearly always the same way: fill the memory once, at creation, and never touch it again. This chapter looks at the other ways to get data into a buffer and move it around, and at one more way to arrange vertex attributes. LearnOpenGL's chapter on the subject has no program of its own; ours does, a patch of water whose surface is recomputed on the CPU every frame.
What a buffer is
A buffer is a block of memory the GPU can read, and on its own nothing more. In OpenGL a buffer gets its meaning from the target it is bound to: the same buffer object is vertex data while bound to GL_ARRAY_BUFFER and indices while bound to GL_ELEMENT_ARRAY_BUFFER. Direct3D asks the question up front instead. When we create a buffer we say, in its BindFlags, every way it may ever be bound (D3D11_BIND_VERTEX_BUFFER, D3D11_BIND_INDEX_BUFFER, D3D11_BIND_CONSTANT_BUFFER, and a few more), and binding it any other way later is an error.
We also say, in its Usage, who will write to it and how often. This is the part that matters for this chapter. There are four choices:
| Usage | GPU | CPU | Typical use |
|---|---|---|---|
| D3D11_USAGE_IMMUTABLE | reads | nothing; the data is given at creation | meshes that never change |
| D3D11_USAGE_DEFAULT | reads and writes | occasional updates through | data that changes now and then; render targets |
| D3D11_USAGE_DYNAMIC | reads | writes through | data rewritten every frame |
| D3D11_USAGE_STAGING | nothing; only copies to and from it | reads and writes through | reading GPU results back |
OpenGL's GL_STATIC_DRAW and GL_DYNAMIC_DRAW are hints that a driver is free to ignore. Direct3D's usages are contracts: an immutable buffer cannot be written, a dynamic one cannot be written with
Filling a buffer
So far every vertex buffer has been immutable, filled by passing the data straight to NULL pointer,
OpenGL's next tool is
// write sizeof(data) bytes at byte 24 of a DEFAULT buffer
D3D11_BOX box = { 24, 0, 0, 24 + sizeof(data), 1, 1 };
context->UpdateSubresource(buffer, 0, &box, &data, 0, 0);
Our texture loading has used
ID3D11DeviceContext_UpdateSubresource(context, cast(texture, *ID3D11Resource), 0, null, img.pixels, cast(img.width * 4, UINT), 0);
The null is the box: no box means the whole subresource, here mip level 0.
The third way, and the one this chapter's program uses, is to ask for a pointer to the buffer's memory and write into it ourselves. OpenGL calls it
// WRITE_DISCARD hands back fresh memory, so the GPU never waits on the CPU.
update_buffer: proc(context: *ID3D11DeviceContext, buffer: *ID3D11Buffer, data: *const void, size: u64) -> void = {
    mapped: D3D11_MAPPED_SUBRESOURCE = {};
    ID3D11DeviceContext_Map(context, cast(buffer, *ID3D11Resource), 0, D3D11_MAP.D3D11_MAP_WRITE_DISCARD, 0, mapped&);
    memcpy(mapped.pData, data, size);
    ID3D11DeviceContext_Unmap(context, cast(buffer, *ID3D11Resource), 0);
}
The other write mode for buffers, D3D11_MAP_WRITE_NO_OVERWRITE, is a promise in the opposite direction: we will only write parts of the buffer that no pending draw is using, so the driver can give us the existing memory without waiting. Together they make the classic pattern for streaming many small pieces of geometry: append with no-overwrite until the buffer is full, then discard and start again at the beginning.
memcpy it, which is still a single copy.
A buffer rewritten every frame
The program draws a square of water 8 units wide, as a grid of 96 by 96 points. The height of each point is a sum of three sine waves running in different directions at different speeds:
wave_height: proc(x: f32, z: f32, t: f32) -> f32 = {
    return 0.25 * sinf(x * 1.3 + t * 1.7) + 0.15 * sinf(z * 2.1 - t * 1.1) + 0.08 * sinf((x + z) * 3.7 + t * 2.3);
}
A vertex shader could compute this itself. We do it on the CPU on purpose, as a stand-in for all the cases where vertex data really does come from the CPU every frame: cloth or physics simulations, particles, text, debug lines. The positions therefore go into a dynamic buffer, made with no initial data and with CPU write access:
// slot 0: positions, DYNAMIC, rewritten every frame
position_desc: D3D11_BUFFER_DESC = {
    .ByteWidth = cast(points * sizeof(vec3), UINT),
    .Usage = D3D11_USAGE.D3D11_USAGE_DYNAMIC,
    .BindFlags = D3D11_BIND_VERTEX_BUFFER,
    .CPUAccessFlags = D3D11_CPU_ACCESS_WRITE,
};
position_buffer: *ID3D11Buffer = null;
ID3D11Device_CreateBuffer(device, position_desc&, null, position_buffer&);
It is the same recipe as
// update the positions, then copy them into the dynamic buffer
for (z: u32 = 0; z < grid; z += 1) {
    for (x: u32 = 0; x < grid; x += 1) {
        wx: f32 = (cast(x, f32) / cast(grid - 1, f32) - 0.5) * grid_size;
        wz: f32 = (cast(z, f32) / cast(grid - 1, f32) - 0.5) * grid_size;
        positions[z * grid + x] = v3(wx, wave_height(wx, wz, current_frame), wz);
    }
}
update_buffer(context, position_buffer, positions, points * sizeof(vec3));
Since we write every byte, discarding is exactly right. The points are joined into triangles by an index buffer, built once at startup, two triangles per grid square, and that never changes: an immutable buffer. So is the water's colour, and that brings us to the second topic.
Batching vertex attributes
Every vertex buffer so far has been 123123123. Another option is to keep each attribute in a block of its own, all positions, then all normals, then all uvs: 111222333. Data loaded from files often comes this way, one array per attribute, and keeping it so saves interleaving it ourselves.
LearnOpenGL does it by writing the three arrays one after another into a single buffer with
For our water there is a good reason to split them beyond convenience: the positions change every frame, and the colours never do. In one interleaved buffer, the unchanging colours would have to be rewritten every frame along with the positions. In two buffers, we only rewrite what changes. The input layout says which slot each attribute comes from:
layout: [2]D3D11_INPUT_ELEMENT_DESC = {
    { .SemanticName = "POSITION", .Format = DXGI_FORMAT.DXGI_FORMAT_R32G32B32_FLOAT, .InputSlot = 0 },
    { .SemanticName = "COLOR", .Format = DXGI_FORMAT.DXGI_FORMAT_R32G32B32_FLOAT, .InputSlot = 1 },
};
Both attributes start at byte 0 of their vertex, since each slot holds only one attribute. The colours, a blue that brightens toward the near edge of the water, are computed once and go into an immutable buffer like any mesh:
// slot 1: colours, IMMUTABLE, uploaded once
color_buffer: *ID3D11Buffer = create_buffer(device, D3D11_BIND_VERTEX_BUFFER, colors, points * sizeof(vec3));
index_buffer: *ID3D11Buffer = create_buffer(device, D3D11_BIND_INDEX_BUFFER, indices, index_count * 4);
At draw time, vec3, 12 bytes:
buffers: [2]*ID3D11Buffer = { position_buffer, color_buffer };
strides: [2]UINT = { 12, 12 };
offsets: [2]UINT = { 0, 0 };
ID3D11DeviceContext_IASetPrimitiveTopology(context, D3D11_PRIMITIVE_TOPOLOGY.D3D11_PRIMITIVE_TOPOLOGY_TRIANGLELIST);
ID3D11DeviceContext_IASetVertexBuffers(context, 0, 2, buffers[0]&, strides[0]&, offsets[0]&);
ID3D11DeviceContext_IASetIndexBuffer(context, index_buffer, DXGI_FORMAT.DXGI_FORMAT_R32_UINT, 0);
ID3D11DeviceContext_RSSetState(context, wire_state);
ID3D11DeviceContext_DrawIndexed(context, cast(index_count, UINT), 0, 0);
ID3D11DeviceContext_RSSetState(context, raster_state);
An index of 517 fetches position 517 from slot 0 and colour 517 from slot 1. The vertex shader cannot tell that its inputs came from two places; the input layout put them back together:
// POSITION comes from vertex buffer slot 0 and COLOR from slot 1; the
// shader cannot tell, the input layout joins them.
water_vertex vs_main(float3 position : POSITION, float3 color : COLOR)
{
    water_vertex o;
    o.position = mul(projection, mul(view, float4(position, 1.0)));
    // Crests a little brighter, so the motion reads even in wireframe.
    o.color = color * (0.8 + position.y);
    return o;
}
The water is drawn in wireframe, with the rasterizer state from Hello Triangle, because a flat-coloured surface with no lighting would hide the waves; the grid lines show them. For the same reason the vertex shader scales the colour by the height, brighter on the crests and darker in the troughs.
LearnOpenGL's layout, three blocks in one buffer, also works in Direct3D: bind the same buffer to three slots, with offsets of 0, the size of the positions, and the size of the positions plus normals, and give each slot its own stride. Which arrangement is faster depends on the hardware; interleaved data is the usual default, since a vertex shader invocation then finds all its inputs next to each other in memory. Split buffers win when, as here, some attributes change and others do not, or when some passes need only some attributes: a depth-only pass that reads only positions touches only the position buffer.
Copying buffers
Once data is on the GPU, we may want to copy it into another buffer without bringing it back to the CPU. OpenGL's
CopyResource (destination, source) copies a whole resource into another of the same size and type.CopySubresourceRegion copies part of one: for buffers, a D3D11_BOX gives the source byte range, and an x coordinate the destination offset.
// copy 8 floats from the start of vb1 to the start of vb2
D3D11_BOX box = { 0, 0, 0, 8 * sizeof(float), 1, 1 };
context->CopySubresourceRegion(vb2, 0, 0, 0, 0, vb1, 0, &box);
Copies run on the GPU, in order with the draws around them, so a copy issued after a draw sees what that draw left behind. The destination may not be immutable, and the two resources must be compatible: a buffer to a buffer, a texture to a texture of the same format family. Copying into a staging buffer and mapping it for reading is how data computed on the GPU is brought back to the CPU, though the map then has to wait for the GPU to catch up.
With these, buffers become more than places to park meshes. The next chapter puts a constant buffer to work across many shaders at once, and Instancing uses a second vertex slot for data that advances once per object instead of once per vertex.
The full program is here, and its shader here.
Additional resources
- D3D11_USAGE: the four usages and what each allows.
- How to: use dynamic resources:
Map with discard and no-overwrite. - CopySubresourceRegion: copying parts of buffers and textures.
- LearnOpenGL's Advanced Data: the OpenGL version of this chapter.
Exercises
- Change the program to keep positions and colours interleaved in one dynamic buffer, 24 bytes per vertex. What does the input layout become, and how much more data is copied per frame?
- Make the colour buffer D3D11_USAGE_DEFAULT and, when a key is pressed, give the water a new colour with
UpdateSubresource . - Move the wave computation into the vertex shader: send a flat grid once, pass the time in a constant buffer, and compute the height from
position.xandposition.z. The dynamic buffer is then no longer needed at all.