Diffuse irradiance
Because it gathers light from every direction around an object, IBL is in effect a much better version of the ambient term, and even a rough stand-in for global illumination. For PBR that makes a big difference: the metals at the end of the last chapter looked dark and wrong precisely because there was nothing around them to reflect.
Let's look at the reflectance equation again:
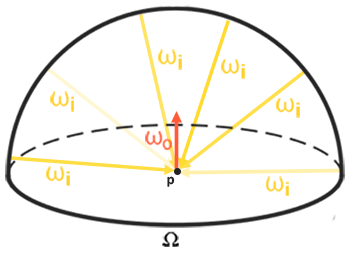
\[ L_o(p,\omega_o) = \int\limits_{\Omega} \left( k_d\frac{c}{\pi} + k_s\frac{D\,F\,G}{4(\omega_o \cdot n)(\omega_i \cdot n)} \right) L_i(p,\omega_i)\, (n \cdot \omega_i)\, d\omega_i \]Our job, as before, is to evaluate the integral over all incoming directions \(\omega_i\) in the hemisphere \(\Omega\). With point lights that was easy, because only four directions carried any light. Now every direction can, which leaves us with two problems to solve:
- we need a way to look up the radiance arriving from any direction \(\omega_i\), and
- evaluating the integral has to be fast enough for real time.
The first is the easy one. An environment cubemap is exactly a function from directions to light: sample it with a direction and it returns the radiance arriving from that way. In HLSL it is one line:
float3 radiance = environment.Sample(linear_clamp, wi).rgb;The second is harder. Doing the integral properly means sampling the environment in a great many directions, for every pixel, every frame, which is far too slow. So we will precompute as much of it as we can. To see what can be precomputed, notice that the BRDF is a sum of a diffuse part and a specular part, so the integral splits into two integrals that we can handle one at a time:
\[ L_o(p,\omega_o) = \int\limits_{\Omega} \left(k_d\frac{c}{\pi}\right) L_i(p,\omega_i)\, (n \cdot \omega_i)\, d\omega_i + \int\limits_{\Omega} \left(k_s\frac{D\,F\,G}{4(\omega_o \cdot n)(\omega_i \cdot n)}\right) L_i(p,\omega_i)\, (n \cdot \omega_i)\, d\omega_i \]This chapter is about the first one, the diffuse part. The next is about the second.
In the diffuse integral, the Lambert term \(k_d \frac{c}{\pi}\) doesn't depend on \(\omega_i\) at all. The albedo, the refracted fraction and \(\pi\) are the same for every incoming direction, so we can pull them out in front:
\[ L_o(p,\omega_o) = k_d\frac{c}{\pi} \int\limits_{\Omega} L_i(p,\omega_i)\, (n \cdot \omega_i)\, d\omega_i \]
What's left inside depends only on the environment and on the orientation of the hemisphere, that is, on the normal \(n\). (It also depends on the position \(p\), but we assume, for now, that every point sees the environment as if from its centre.) A function of one direction is something we can store in a cubemap. So for every direction we can compute the integral once, ahead of time, and store the result in a new cubemap texel pointing that way. Computing it means visiting, for each output direction, a large number of directions over the hemisphere around it and averaging what they see. That kind of operation, where every output value is built from many input values around it, is a
The resulting cubemap stores, for every direction, the total diffuse light that a surface facing that way would receive from the whole environment. It is called an
Here is an environment cubemap beside the irradiance map made from it (images courtesy of Wave Engine, by way of LearnOpenGL):
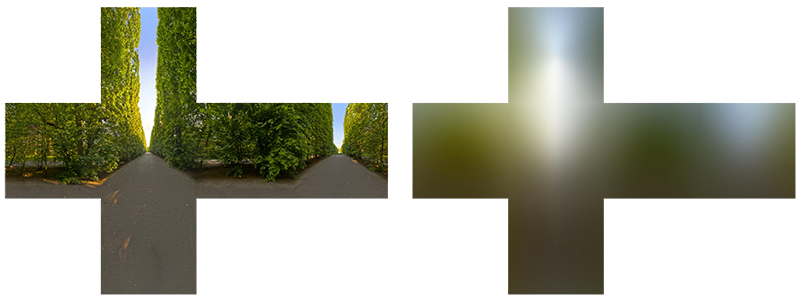
The irradiance map looks like the environment blurred beyond recognition, which is what it is: each texel is an average over half the sphere, so only broad changes in brightness and colour survive. Sampling it with a normal gives that normal's share of the environment's diffuse light.
PBR and HDR
The last chapter showed why PBR needs high dynamic range: lights are given in something like physical units, and the gap between a desk lamp and the sun is enormous. Image based lighting needs it too, and in a more awkward place, because now the light comes from a texture. The cubemaps of the Cubemaps chapter were ordinary 8-bit images, with every value between 0 and 1. That is fine for a background, but as a source of light it is useless: a window and the sun in it would both be stored as 1.0, and the sun would light the scene no more than a white wall. To use an environment as light we need it stored in HDR.
The Radiance HDR file format
The .hdr) is the common way to store such images. It keeps values well above 1, so the sun can be thousands of times brighter than the shadows, but stores them compactly: each pixel is four bytes, three 8-bit mantissas for red, green and blue that share one 8-bit exponent (
Free HDR environments are easy to find (the sIBL Archive and Poly Haven have many). Ours is newport_loft.hdr, a sunny living room. It looks like this:
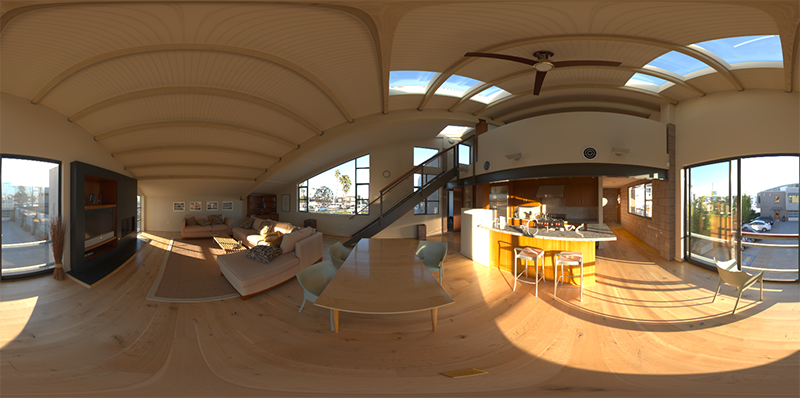
That is not six cube faces but one distorted panorama: the whole sphere of directions unrolled onto a rectangle, longitude across and latitude down, the way a world map unrolls the globe. This is an
Loading an HDR image
LearnOpenGL loads HDR files with stb_image. We don't use stb; our image loader in image.rin reads ordinary images through Windows' own WIC codecs, which don't handle Radiance files, so it has a small reader of its own for them. It returns linear floating-point pixels:
image_hdr: struct = {
    pixels: [*]vec4;     // linear RGB, a = 1
    width: i32;
    height: i32;
}
A Radiance file starts with a text header, ended by a blank line, then a line giving the size, such as -Y 800 +X 1600: 800 rows from top to bottom, 1600 pixels across. The pixel rows follow, each one compressed with a simple run-length encoding, one channel at a time. The reader expands each row into RGBE bytes and then turns every pixel into floats:
e: i32 = cast(row[x * 4 + 3], i32);
// mantissa / 256 * 2^(e - 128), and e = 0 means black
scale: f32 = e == 0 ? 0.0 : ldexpf(1.0, e - 136);
result.pixels[y * w + x] = v4(cast(row[x * 4], f32) * scale, cast(row[x * 4 + 1], f32) * scale, cast(row[x * 4 + 2], f32) * scale, 1.0);
Each mantissa byte is a fraction of 256, and the exponent is stored with an offset of 128, so a channel's value is \(m / 256 \cdot 2^{e - 128}\), or \(m \cdot 2^{e - 136}\).
The floats go straight into a texture:
// the HDR environment as a float texture
load_hdr: proc(device: *ID3D11Device, path: [*]const char) -> *ID3D11ShaderResourceView = {
    img: image_hdr = image_load_hdr(path);
    ...
    desc: D3D11_TEXTURE2D_DESC = {
        .Width = cast(img.width, UINT),
        .Height = cast(img.height, UINT),
        .MipLevels = 1,
        .ArraySize = 1,
        .Format = DXGI_FORMAT.DXGI_FORMAT_R32G32B32A32_FLOAT,
        .SampleDesc = { .Count = 1 },
        .BindFlags = D3D11_BIND_SHADER_RESOURCE,
    };
    init: D3D11_SUBRESOURCE_DATA = {
        .pSysMem = img.pixels,
        .SysMemPitch = cast(img.width * 16, UINT),
    };
    ...
}
DXGI_FORMAT_R32G32B32A32_FLOAT is four 32-bit floats per texel, 16 bytes, which is why the row pitch is width * 16. There is a three-channel 32-bit float format too, but whether hardware can filter it is optional, and the alpha costs us nothing worth worrying about for one texture.
From equirectangular to cubemap
We could sample the panorama directly every time we need the environment, but turning a direction into panorama coordinates costs an
The conversion draws a unit cube from the inside, through a camera at its centre, once for each of the six faces of a cubemap, with each face as the render target. The vertex shader passes on the cube's local position, which, seen from the centre, is the direction to look up:
// The unit cube's corners are the directions to look up, drawn through
// one face's view.
struct sky_vertex
{
    float4 position : SV_Position;
    float3 direction : DIRECTION;
};

sky_vertex vs_main(float3 position : POSITION)
{
    sky_vertex o;
    o.direction = position;
    o.position = mul(projection, mul(view, float4(position, 1.0)));
    return o;
}
The pixel shader turns that direction into the point of the panorama that shows it, with a little trigonometry: the angle around the vertical axis gives u, and the angle above or below the horizon gives v.
// a direction to a point on the panorama: longitude across, latitude down
// (D3D's v runs down the image, so the top row is straight up)
float2 equirect_uv(float3 d)
{
    return float2(atan2(d.z, d.x) / (2.0 * PI) + 0.5, 0.5 - asin(d.y) / PI);
}

float4 ps_main(sky_vertex p) : SV_Target
{
    return float4(equirect.SampleLevel(linear_wrap, equirect_uv(normalize(p.direction)), 0).rgb, 1.0);
}
0.5 - ... where LearnOpenGL adds. The direction must be normalized first; the interpolated cube position is not unit length. The wrapping sampler at s0 lets the filter blend across the left and right edges of the panorama, which meet behind us.
Now the target. A cubemap in Direct3D is a 2D texture array of six slices, with a flag that says to treat it as a cube:
create_cube_target: proc(device: *ID3D11Device, size: i32, mips: UINT, generate_mips: b32) -> cube_target = {
    t: cube_target = { .size = size };
    desc: D3D11_TEXTURE2D_DESC = {
        .Width = cast(size, UINT),
        .Height = cast(size, UINT),
        .MipLevels = mips,
        .ArraySize = 6,
        .Format = DXGI_FORMAT.DXGI_FORMAT_R16G16B16A16_FLOAT,
        .SampleDesc = { .Count = 1 },
        .BindFlags = D3D11_BIND_RENDER_TARGET | D3D11_BIND_SHADER_RESOURCE,
        .MiscFlags = D3D11_RESOURCE_MISC_TEXTURECUBE,
    };
    if (generate_mips) { desc.MiscFlags = D3D11_RESOURCE_MISC_TEXTURECUBE | D3D11_RESOURCE_MISC_GENERATE_MIPS; }
    ID3D11Device_CreateTexture2D(device, desc&, null, t.texture&);
    view: D3D11_SHADER_RESOURCE_VIEW_DESC = {
        .Format = desc.Format,
        .ViewDimension = D3D11_SRV_DIMENSION.D3D11_SRV_DIMENSION_TEXTURECUBE,
        .TextureCube = { .MipLevels = 0xffffffff },   // all of them
    };
    ID3D11Device_CreateShaderResourceView(device, cast(t.texture, *ID3D11Resource), view&, t.srv&);
    return t;
}
It is both a render target, so we can draw into it, and a shader resource, so we can sample it afterwards. Half floats, DXGI_FORMAT_R16G16B16A16_FLOAT, keep the HDR range at half the cost of 32-bit floats; Direct3D has no three-channel half-float format, so the fourth channel comes along. The shader resource view is a TEXTURECUBE view, which is what lets a shader declare it as a TextureCube and sample it with a direction. The environment cube is 512 by 512 per face, with a full mip chain that the hardware can generate for us; the next chapter needs the mips.
env_cubemap: cube_target = create_cube_target(device, 512, 0, 1);
shader_use(context, equirect_shader&);
bind_texture(context, 0, hdr_texture);
render_to_cube(device, context, env_cubemap&, 0, transforms_buffer, cube_vb);
unbind_textures(context);
ID3D11DeviceContext_GenerateMips(context, env_cubemap.srv);
render_to_cube: proc(device: *ID3D11Device, context: *ID3D11DeviceContext, target: *cube_target, mip: UINT,
                     constants: *ID3D11Buffer, cube_vb: *ID3D11Buffer) -> void = {
    targets: [6]vec3 = { v3(1.0, 0.0, 0.0), v3(-1.0, 0.0, 0.0), v3(0.0, 1.0, 0.0), v3(0.0, -1.0, 0.0), v3(0.0, 0.0, 1.0), v3(0.0, 0.0, -1.0) };
    ups: [6]vec3 = { v3(0.0, -1.0, 0.0), v3(0.0, -1.0, 0.0), v3(0.0, 0.0, 1.0), v3(0.0, 0.0, -1.0), v3(0.0, -1.0, 0.0), v3(0.0, -1.0, 0.0) };
    t: transforms = {
        .projection = m4_mul(m4_scale(v3(1.0, -1.0, 1.0)), m4_perspective(radians(90.0), 1.0, 0.1, 10.0)),
    };
    size: i32 = target[0].size shr cast(mip, i32);
    ...
    for (face: UINT = 0; face < 6; face += 1) {
        rtv_desc: D3D11_RENDER_TARGET_VIEW_DESC = {
            .Format = DXGI_FORMAT.DXGI_FORMAT_R16G16B16A16_FLOAT,
            .ViewDimension = D3D11_RTV_DIMENSION.D3D11_RTV_DIMENSION_TEXTURE2DARRAY,
            .Texture2DArray = { .MipSlice = mip, .FirstArraySlice = face, .ArraySize = 1 },
        };
        rtv: *ID3D11RenderTargetView = null;
        ID3D11Device_CreateRenderTargetView(device, cast(target[0].texture, *ID3D11Resource), rtv_desc&, rtv&);
        ID3D11DeviceContext_OMSetRenderTargets(context, 1, rtv&, null);
        t.view = m4_look_at(v3(0.0, 0.0, 0.0), targets[face], ups[face]);
        draw_vertices(context, constants, t&, cube_vb, 36, m4_identity());
        ID3D11RenderTargetView_Release(rtv);
    }
}
For each face it makes a render target view onto exactly one slice of the array, at one mip level, binds it, and draws the cube with a camera looking out through that face. The faces are in Direct3D's order (+x, -x, +y, -y, +z, -z), and a field of view of 90 degrees with an aspect ratio of 1 makes each view cover exactly one face. There is no depth buffer, the null in size shr mip, which will matter in the next chapter.
The targets and ups are LearnOpenGL's six capture views, but the projection has an extra m4_scale(v3(1.0, -1.0, 1.0)) that flips y. The reason is in the comment above the function. The faces of a cubemap are laid out as if seen from inside the cube by a left-handed camera: on the +x face, for example, u runs towards -z and v runs down towards -y. A right-handed look-at camera facing +x with +y up would see +z on its right, a mirror image of what the face expects. The capture views fix the left and right by turning each side camera upside down (up is -y). OpenGL then gets the picture upright again for free, because it stores the rows of a render target bottom first. Direct3D stores them top first, so we turn the image back over ourselves, by negating y after projection. Mirroring one axis also reverses the winding order of every triangle, which is one more reason culling stays off in these lessons.
Finally, the input texture is unbound:
// A texture cannot be read while it is bound as a target, so the slots are
// emptied before drawing into one.
unbind_textures: proc(context: *ID3D11DeviceContext) -> void = {
    views: [8]*ID3D11ShaderResourceView = {};
    ID3D11DeviceContext_PSSetShaderResources(context, 0, 8, views[0]&);
}
Direct3D will not let a resource be bound for reading and for writing at the same time. The next step reads the cube we just wrote, and the one after draws into another cube; if a view of a texture is still in a shader slot when that texture is bound as a target, the runtime quietly unbinds it (and the debug layer complains). Emptying the slots ourselves keeps every step's bindings explicit.
Showing the environment
To see the result, the program draws the cube map as a skybox around the scene, much as in Cubemaps:
sky_vertex vs_main(float3 position : POSITION)
{
    sky_vertex o;
    o.direction = position;
    // the view without its translation, and z = w: the far plane, as in 4.6.1
    float4x4 rotation = view;
    rotation[0][3] = 0.0;
    rotation[1][3] = 0.0;
    rotation[2][3] = 0.0;
    o.position = mul(projection, mul(rotation, float4(position, 1.0))).xyww;
    return o;
}
The skybox must not move with the camera, so the translation is removed from the view matrix. LearnOpenGL does that with mat4(mat3(view)); we clear the translation directly. Our matrices multiply column vectors (mul(M, v) is \(M v\)), so the translation sits in the fourth column, which with row-major storage is element 3 of each of the first three rows. Writing .xyww makes z equal to w, so after the perspective divide every skybox pixel lands at depth 1.0, the far end of Direct3D's 0 to 1 range. With the depth buffer cleared to 1.0, that only passes a test of "less or equal", so the skybox is drawn last with its own depth state, which also leaves the depth buffer unwritten:
sky_depth_desc: D3D11_DEPTH_STENCIL_DESC = {
    .DepthEnable = 1,
    .DepthWriteMask = D3D11_DEPTH_WRITE_MASK.D3D11_DEPTH_WRITE_MASK_ZERO,
    .DepthFunc = D3D11_COMPARISON_FUNC.D3D11_COMPARISON_LESS_EQUAL,
};
// render skybox (render as last to prevent overdraw)
shader_use(context, background_shader&);
bind_texture(context, 0, env_cubemap.srv);
ID3D11DeviceContext_OMSetDepthStencilState(context, sky_depth, 0);
draw_vertices(context, transforms_buffer, t&, cube_vb, 36, m4_identity());
ID3D11DeviceContext_OMSetDepthStencilState(context, null, 0);The pixel shader samples the cube with the interpolated direction. The environment is HDR, so it needs tone mapping like everything else we draw; the sRGB back buffer takes care of the gamma, as before:
float4 ps_main(sky_vertex p) : SV_Target
{
    float3 color = env.SampleLevel(linear_clamp, p.direction, 0).rgb;
    return float4(color / (color + 1.0), 1.0);
}
It takes some setup to get here: we read an HDR file, unrolled panorama into cube, and drew the cube around us. In return we have a small, reusable system for drawing into all six faces of a cubemap, and that is exactly what the convolution needs.
Cubemap convolution
Back to the goal. For every direction, we want the diffuse integral of the environment over the hemisphere facing that way:
\[ L_o(p,\omega_o) = k_d\frac{c}{\pi} \int\limits_{\Omega} L_i(p,\omega_i)\, (n \cdot \omega_i)\, d\omega_i \]The environment cubemap gives us \(L_i\) for any \(\omega_i\). Sampling every direction is impossible, as there are infinitely many, but a large finite number of them, spread evenly over the hemisphere, gives a good estimate. That is still far too much work per pixel per frame, so we do it once, for every orientation of the hemisphere, and store the results. Then shading a pixel needs a single lookup, by its normal:
float3 ambient = kd * irradiance_map.Sample(linear_clamp, n).rgb * albedo * ao;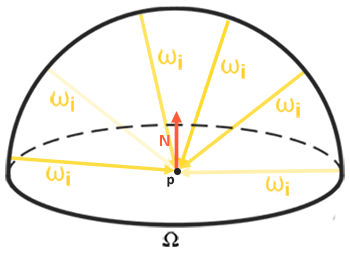
To produce the irradiance map, we take the environment cube, convolve it in a pixel shader, and write the result into another cube. That is exactly what
Integrating over solid angle is awkward, so we change variables to the two angles of spherical coordinates: \(\phi\), the azimuth, going round the hemisphere from 0 to \(2\pi\), and \(\theta\), the angle from the normal, going from 0 at the top to \(\frac{\pi}{2}\) at the rim.
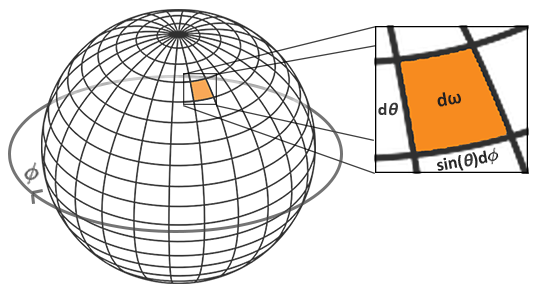
A small step \(d\theta\) by \(d\phi\) covers a patch of the sphere whose size is \(\sin\theta\, d\theta\, d\phi\): the rings of constant \(\theta\) get shorter towards the pole, in proportion to \(\sin\theta\). So \(d\omega_i = \sin\theta\, d\theta\, d\phi\). And \(n \cdot \omega_i\) is \(\cos\theta\) by definition of \(\theta\). The integral becomes:
\[ L_o(p,\phi_o,\theta_o) = k_d\frac{c}{\pi} \int_{\phi = 0}^{2\pi} \int_{\theta = 0}^{\frac{1}{2}\pi} L_i(p,\phi_i,\theta_i) \cos(\theta) \sin(\theta)\, d\theta\, d\phi \]Now we can approximate it with a Riemann sum: step through both angles in small, equal steps, and add up. With \(N_1\) steps in \(\phi\) and \(N_2\) in \(\theta\), each step is \(\Delta\phi = 2\pi / N_1\) by \(\Delta\theta = \frac{\pi}{2} / N_2\), so every term carries a factor \(\Delta\phi\,\Delta\theta = \pi^2 / (N_1 N_2)\). Taking that and the \(\frac{1}{\pi}\) of Lambert together:
\[ L_o(p,\phi_o,\theta_o) \approx k_d\, c\, \frac{\pi}{N_1 N_2} \sum_{\phi} \sum_{\theta} L_i(p,\phi_i,\theta_i) \cos(\theta) \sin(\theta) \]The \(\cos\theta\) is the usual weakening of light that arrives at an angle, and the \(\sin\theta\) compensates for the samples near the top of the hemisphere covering less of it than the samples near the rim. In HLSL:
// Diffuse irradiance: for the normal `n` (this pixel's direction), the
// average of the environment over the hemisphere around it, each direction
// weighted by cos(theta), the way a matte surface receives it.
TextureCube env : register(t0);
SamplerState linear_clamp : register(s1);

static const float PI = 3.14159265359;

float4 ps_main(sky_vertex p) : SV_Target
{
    float3 n = normalize(p.direction);
    // any two directions perpendicular to n and to each other
    float3 up = abs(n.y) < 0.999 ? float3(0.0, 1.0, 0.0) : float3(1.0, 0.0, 0.0);
    float3 right = normalize(cross(up, n));
    up = cross(n, right);

    float3 sum = 0.0;
    float count = 0.0;
    float step = 0.025;
    for (float phi = 0.0; phi < 2.0 * PI; phi += step)
    {
        for (float theta = 0.0; theta < 0.5 * PI; theta += step)
        {
            float3 local = float3(sin(theta) * cos(phi), sin(theta) * sin(phi), cos(theta));
            float3 d = local.x * right + local.y * up + local.z * n;
            // cos(theta) for the angle of incidence, sin(theta) because the
            // rings of the hemisphere shrink towards the pole
            sum += env.SampleLevel(linear_clamp, d, 0).rgb * cos(theta) * sin(theta);
            count += 1.0;
        }
    }
    return float4(PI * sum / count, 1.0);
}
First we need a frame around the normal, two more directions perpendicular to it and to each other, so the hemisphere can be described in local terms and turned to face \(n\). We cross the normal with world up, unless the normal is itself nearly vertical, in which case the cross product would be close to zero and we use the x axis instead. (LearnOpenGL's version always uses world up, which would break down for a normal pointing exactly up or down.)
The two loops step through \(\phi\) and \(\theta\) in steps of 0.025 radians, which is about 250 by 63 directions, roughly sixteen thousand samples per texel. Each pair of angles becomes a direction in local space by the usual spherical-to-Cartesian formula, with z along the normal; multiplying by the frame turns it to world space, and we sample the environment there. The result is PI * sum / count, the sum from the formula above except for \(k_d\) and \(c\). Those depend on the material, which the convolution knows nothing about, so the PBR shader multiplies them in when it looks the map up. Notice that the \(\frac{1}{\pi}\) of Lambert's term is already accounted for here, which is why there is no division by \(\pi\) in the lookup line above.
A smaller step gives a more accurate result at a higher cost. This shader is the slowest thing in the program, and it only runs at startup.
The irradiance map is a cube of 32 by 32 per face, with a single mip level:
// pbr: an irradiance cubemap, by convolving the environment
// ---------------------------------------------------------
irradiance_map: cube_target = create_cube_target(device, 32, 1, 0);
shader_use(context, irradiance_shader&);
bind_texture(context, 0, env_cubemap.srv);
render_to_cube(device, context, irradiance_map&, 0, transforms_buffer, cube_vb);
unbind_textures(context);
32 by 32 is plenty, because the irradiance map has no fine detail: each texel is an average over half the sphere, so neighbouring texels hardly differ, and the bilinear filter fills in between them. Unlike LearnOpenGL, which has to resize its framebuffer's depth attachment for the new size, there is nothing else to change;
If you draw the background from the irradiance map instead of the environment, you should see the room smeared into soft patches of colour: warm and bright towards the windows, darker below. That is the first exercise.
PBR and indirect irradiance lighting
The irradiance map holds the diffuse half of the reflectance integral for light arriving from the environment. It is light that doesn't come from a light source but from the surroundings, which is exactly what the improvised ambient term of the last chapter stood in for. So the 0.03 constant goes, and the irradiance map takes its place. It is bound at t0, with the clamping sampler at s1:
TextureCube irradiance_map : register(t0);
SamplerState linear_clamp : register(s1);
Looking it up by the normal gives the irradiance at the pixel. But light from the environment is subject to the same split between reflection and refraction as light from a lamp: some of it reflects off the surface (the specular half, which the next chapter adds) and only the rest is available as diffuse. So, as with direct light, we work out \(k_s\) with Fresnel and take \(k_d\) as what is left, scaled down for metals. With direct light, Fresnel used the halfway vector between the light and the eye. Environment light comes from the whole hemisphere at once, so there is no single halfway vector; instead we use the angle between the normal and the view direction, the nearest thing to a single angle that describes how we look at the surface.
That leaves one problem. The halfway-vector Fresnel of a rough surface is spread over many microfacet orientations, so a rough surface doesn't get much brighter at grazing angles. Using \(n \cdot v\) loses that, and gives every surface the strong rim of a smooth one. On rough dielectrics it shows as a too-bright edge (LearnOpenGL's picture exaggerates it to make the point):
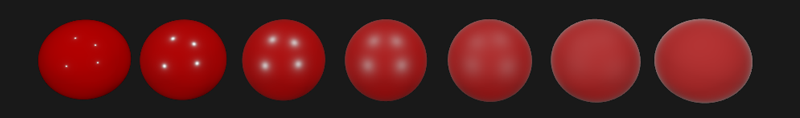
Sébastien Lagarde suggested a fix: let the grazing-angle limit of Fresnel depend on roughness, so rough surfaces rise towards \(1 - roughness\) instead of towards 1:
// For image based light, where there is no single halfway vector: rough
// surfaces get less of the grazing-angle boost.
float3 fresnel_schlick_roughness(float cos_theta, float3 f0, float roughness)
{
    return f0 + (max((1.0 - roughness).xxx, f0) - f0) * pow(saturate(1.0 - cos_theta), 5.0);
}
The
// ambient lighting from the environment: only the diffuse part so far;
// the specular share (Fresnel) is what the surface does not scatter
float3 f0 = lerp(0.04.xxx, albedo, metallic);
float3 ks = fresnel_schlick_roughness(max(dot(n, v), 0.0), f0, roughness);
float3 kd = (1.0 - ks) * (1.0 - metallic);
float3 ambient = kd * irradiance_map.Sample(linear_clamp, n).rgb * albedo * ao;

float3 color = ambient + lo;
return float4(color / (color + 1.0), 1.0);
The image based part of the shader is a single texture lookup; all the hard work was in building the map. The four point lights of the previous chapter are still there, in lo, and the ambient occlusion now darkens real ambient light.
The scene is the grid of spheres from Lighting, metallic increasing upwards and roughness to the right, now standing in the living room:
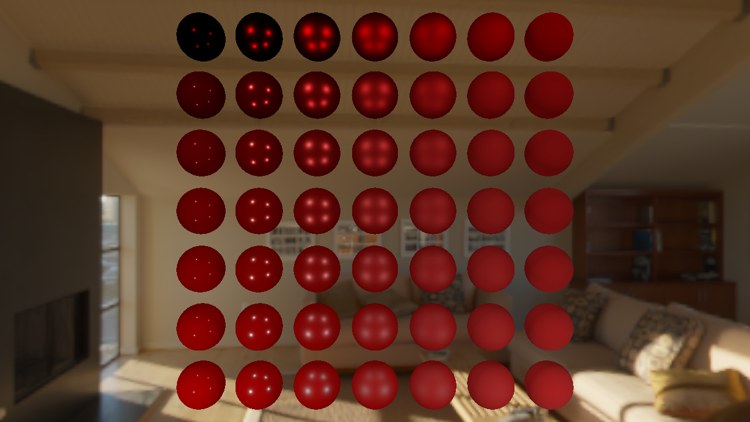
The dielectric spheres in the lower rows now receive the room's light, and are clearly brighter than under the four lamps alone. The metals in the top rows are still almost black apart from their highlights, which is to be expected: a metal has no diffuse light, and diffuse is all we have added. They need reflections, which are the subject of the next chapter. Even so, the spheres already look much more as though they are in the room rather than pasted in front of it.
The full program is here. Its shaders are equirectangular_to_cubemap.hlsl, irradiance_convolution.hlsl, background.hlsl and pbr.hlsl. LearnOpenGL splits this into two programs, one that only converts and shows the environment and one that adds the convolution; ours is both in one.
Additional resources
- Physically based rendering, Coding Labs: the rendering equation and why, and how, to build an irradiance map.
- The Mathematics of Shading, Scratchapixel: spherical coordinates, solid angles and integrals over the sphere, explained slowly.
- RGBE file format: Bruce Walter's notes and reference code for reading and writing Radiance files.
- Introduction to textures in Direct3D 11: texture arrays, cube textures and their mip levels, and how views select parts of them.
- LearnOpenGL's Diffuse irradiance: the OpenGL original of this chapter.
Exercises
- Bind irradiance_map instead of env_cubemap for the skybox, so the background shows the irradiance map. Does it look like a blurred version of the room, brighter where the windows are?
- Change the step of the convolution to 0.1, then to 0.01, and compare the startup time and the result on the spheres. How large can the step get before you can see a difference?
- Replace
fresnel_schlick_roughness in the ambient term with plainfresnel_schlick , and look at the edges of the rough dielectric spheres in the bottom right of the grid. - Skip the cubemap: sample the equirectangular texture directly in
background.hlsl, usingequirect_uv . (You will need to bind the HDR texture in place of the cube; the wrapping sampler is still bound ats0.) Then look straight up and straight down: what happens at the poles?